Q: Why is “error analysis” so important in AI evals, and how is it performed?
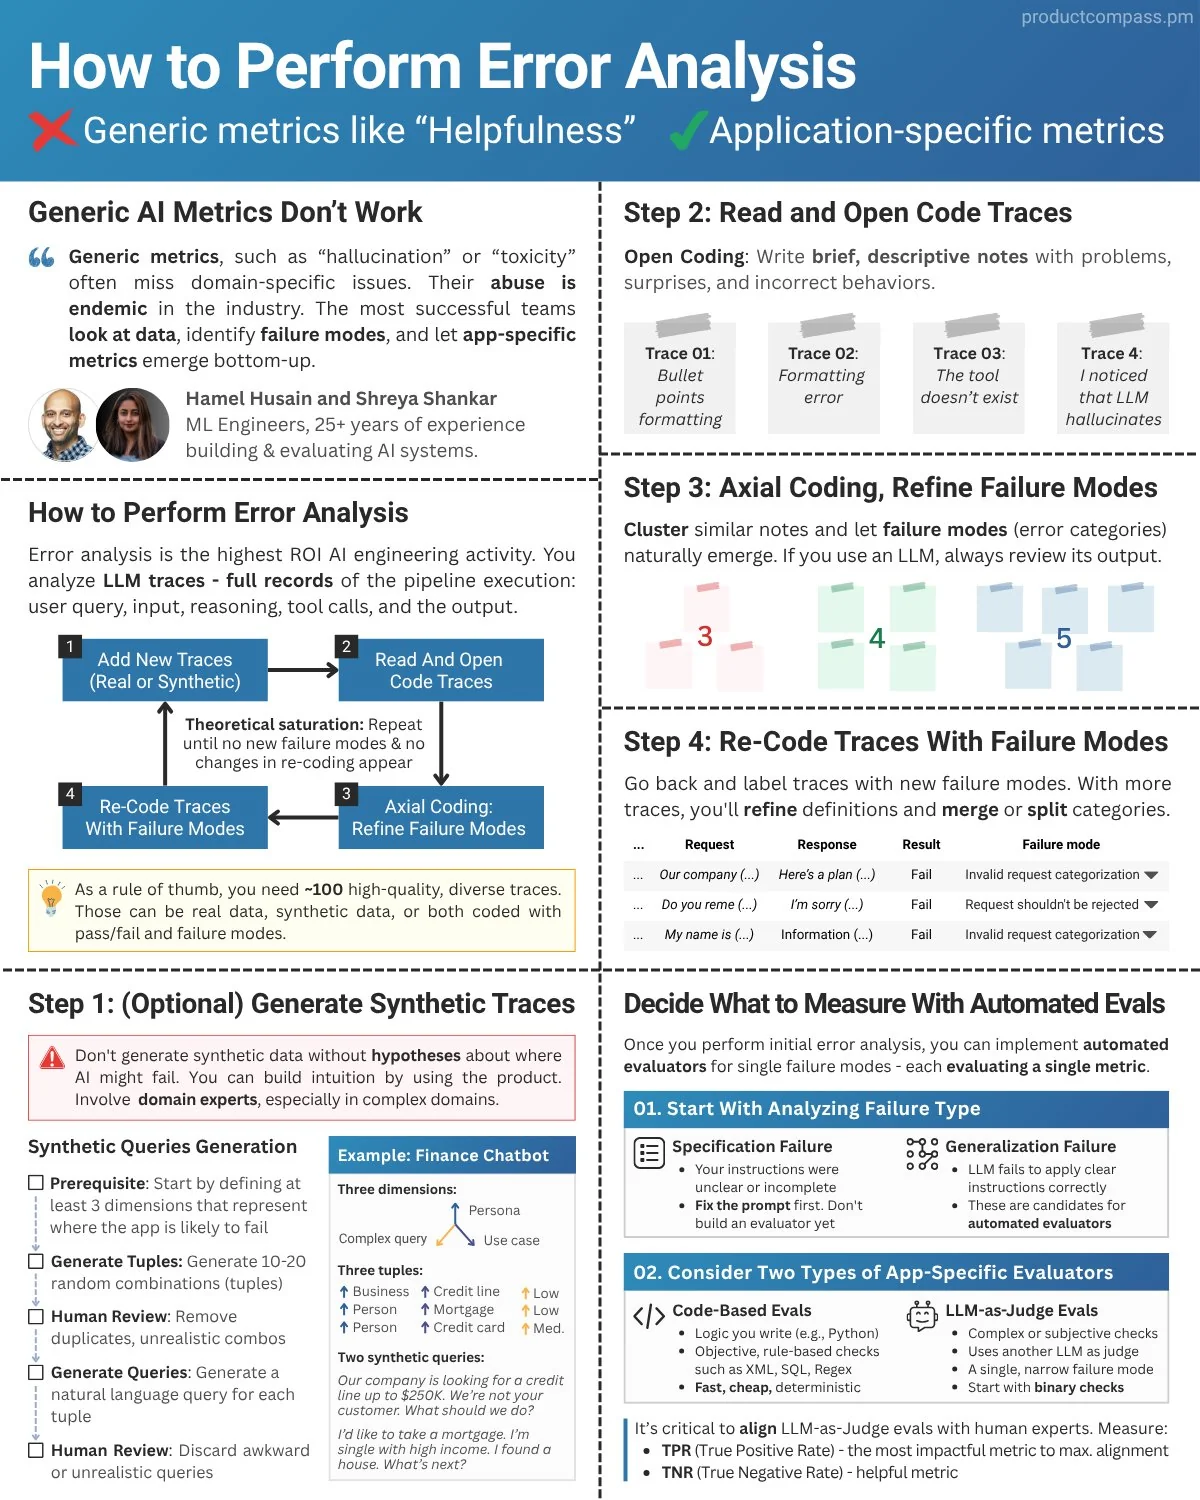
Error analysis is the most important activity in evals. Error analysis helps you decide what evals to write in the first place. It allows you to identify failure modes unique to your application and data. The process involves:
1. Creating a Dataset
Gathering representative traces of user interactions with the LLM. If you do not have any data, you can generate synthetic data to get started.
2. Open Coding
Human annotator(s) (ideally a benevolent dictator) review and write open-ended notes about traces, noting any issues. This process is akin to “journaling” and is adapted from qualitative research methodologies. Start by annotating at least 30 traces yourself before reviewing suggestions from an agent. When beginning, it is recommended to focus on noting the first failure observed in a trace, as upstream errors can cause downstream issues, though you can also tag all independent failures if feasible. A domain expert should be performing this step.
3. Axial Coding
Categorize the open-ended notes into a “failure taxonomy.” In other words, group similar failures into distinct categories. Axial coding is the most important step. At the end, count the number of failures in each category. You can use an LLM to help with this step.
4. Iterative Refinement
Have your agent cluster the data and choose a diverse initial sample. After your first 30 annotations, let it search the remaining traces for likely instances of the failures you described. Accept or reject its suggestions and keep iterating until you reach theoretical saturation, meaning new reviews stop revealing failure modes or changing existing ones.
A working pool of roughly 100 diverse traces is a useful guardrail for this human-agent loop. The agent can focus your attention on the most informative traces, so you no longer have to read all 100 sequentially. See how many examples you need for each kind of eval for the full breakdown.
You should frequently revisit this process. There are advanced ways to sample data more efficiently, like clustering, sorting by user feedback, and sorting by high probability failure patterns. Over time, you’ll develop a “nose” for where to look for failures in your data.
Do not skip error analysis. It ensures that the evaluation metrics you develop are supported by real application behaviors instead of counter-productive generic metrics (which most platforms nudge you to use). For examples of how error analysis can be helpful, see this video, or this blog post.
Here is a visualization of the error analysis process by one of our students, Pawel Huryn - including how it fits into the overall evaluation process:
This article is part of our AI Evals FAQ, a collection of common questions (and answers) about LLM evaluation. View all FAQs or return to the homepage.