Q: Can I use Jev for evals?
Yes. Jev from TypeSafe is a general-purpose classifier that you can use for evals. An LLM judge that returns Pass or Fail is also a classifier.
You validate Jev the same way you would any other classifier used for evals, by comparing its predictions against trusted labels. That’s why we’ve crossed out “LLM Judge” in our original flashcard and replaced it with “Classifier for Evals”:
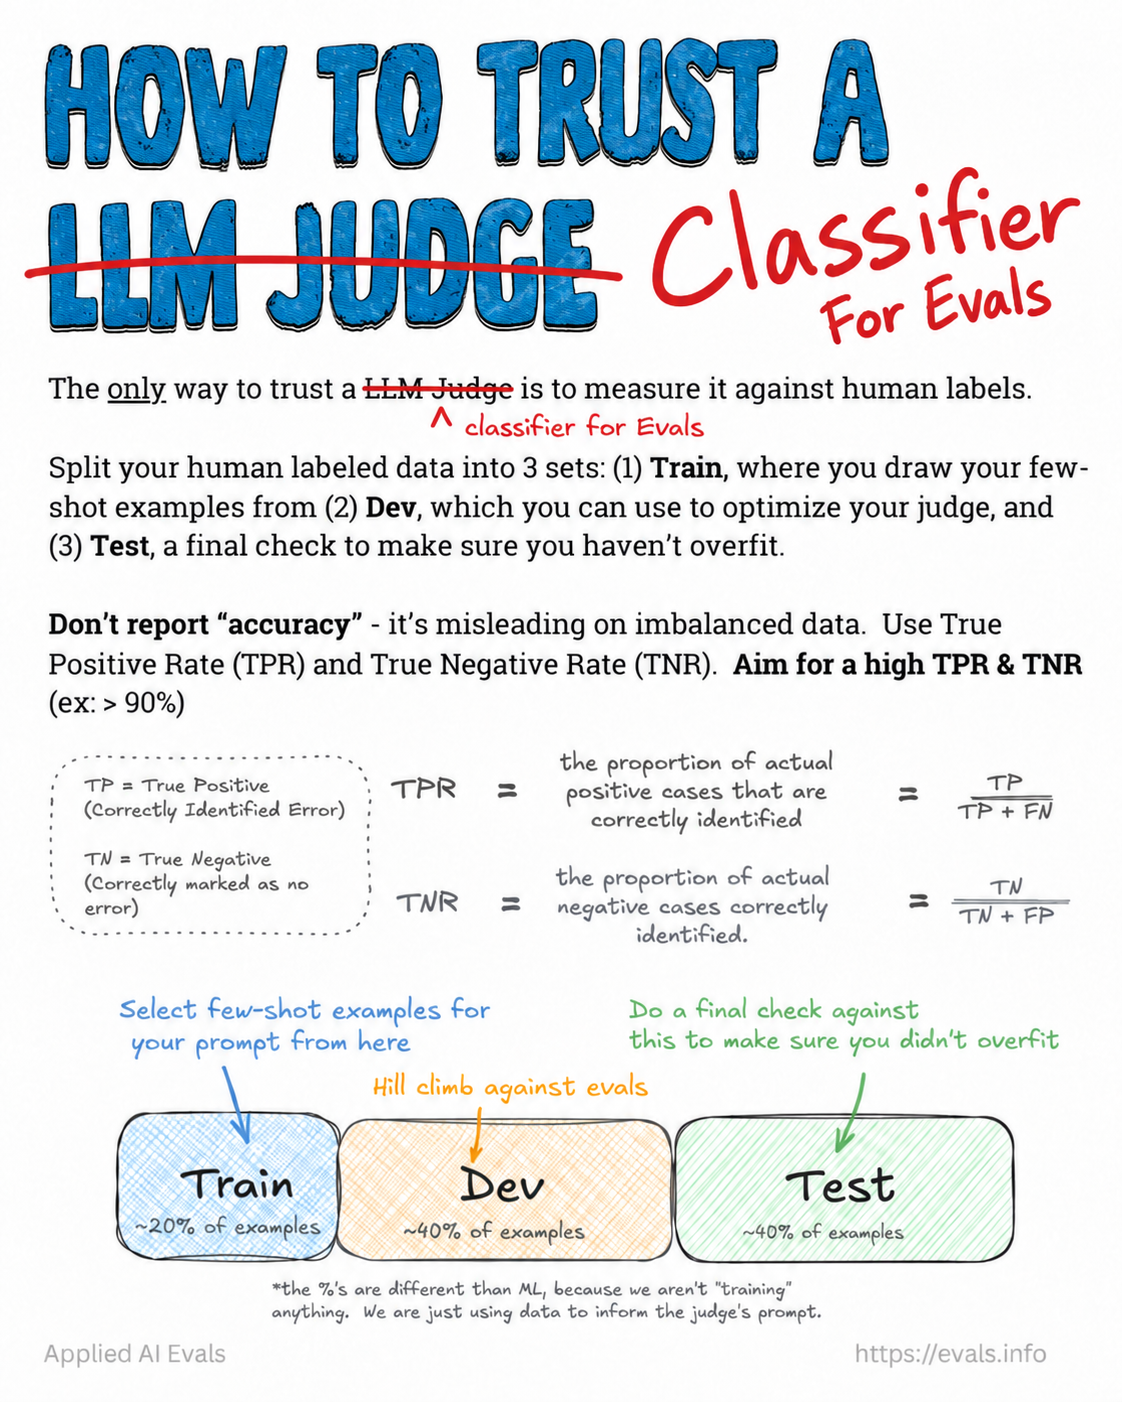
To understand the validation process described in the flashcard, see this post.
The advantage of a fast inexpensive classifier (like Jev) is that it can make automated prompt tuning significantly cheaper and faster. Prompt tuning involves automatically trying changes to the evaluator’s prompt and checking whether its decisions agree more closely with human labels. GEPA is one example of a prompt tuning algorithm. Prompt tuning can sometimes require hundreds or thousands of evaluations, so a lower cost per run can add up to substantial savings.
No single classifier is best for every eval. Validation with human labels help you make trade-offs between accuracy, cost, and speed for your application.
This article is part of our AI Evals FAQ, a collection of common questions (and answers) about LLM evaluation. View all FAQs or return to the homepage.